Data quality determines AI model success because a model can only learn the patterns present in its training data, so errors, gaps and inconsistencies become errors in every prediction. Gartner estimates poor data quality costs organizations an average of $12.9 million a year, and it predicts 60% of AI projects lacking AI-ready data will be abandoned through 2026. Clean, consistent, representative data is the highest-return investment in any AI program.
Every AI vendor pitch opens with the model. Bigger parameters, newer architecture, better benchmark scores. Almost none of them open with the question that actually predicts whether your project will ship: what are you going to feed it?
After more than a decade building data pipelines and machine learning systems for startups and enterprises, we have seen the same pattern repeat. Teams that fix their data before touching the model get to production. Teams that chase the model while hoping the data sorts itself out end up with an expensive pilot that never leaves the lab.
This guide explains the link between data quality and AI model performance in plain language, with the numbers leaders need to make the case internally.
Key Takeaways:
- Poor data quality costs the average organization $12.9 million per year (Gartner).
- Gartner predicts 60% of AI projects without AI-ready data will be abandoned through 2026.
- Only 12% of organizations consider their data of sufficient quality and accessibility for AI (Informatica CDO survey).
- Improving data accuracy, consistency and integrity typically lifts model accuracy more than switching algorithms.
What Does AI Data Quality Actually Mean?
AI data quality is the degree to which a dataset is accurate, complete, consistent, timely and representative of the real-world situations a model will face. Traditional data quality asks whether a report is correct. AI data quality asks whether a model can learn true patterns from the data and apply them to cases it has never seen.
That second standard is stricter. A spreadsheet with 5% duplicate rows produces a slightly wrong total. A training set with 5% duplicates teaches the model that those records matter more than they do, and it carries that bias into every output.
Data quality in artificial intelligence also includes labeling quality. If humans tagged 8% of your support tickets with the wrong category, your classifier will learn to be wrong 8% of the time with full confidence.
Think of it this way. The model is the student, the data is the textbook. A brilliant student with a textbook full of typos still fails the exam.
Why Does Bad Data Cost More Than a Bad Model?
Bad data costs more than a bad model because a model can be swapped in days, while data problems compound across every model, dashboard and decision that touches them. Gartner puts the average cost of poor data quality at $12.9 million per organization per year, and the IBM Institute for Business Value found that over a quarter of organizations lose more than $5 million annually to it.
Those figures are before you add AI. Once a model is in production, every flawed record becomes an automated flawed action: a rejected loan, a missed fraud flag, a wrong inventory order.
Technobrave mini-case: On a recent demand forecasting engagement for a mid-sized distributor, the client wanted to replace their gradient boosting model with a deep learning architecture. We audited the data first and found 14% of SKU records had inconsistent unit-of-measure fields. Fixing that single consistency issue cut forecast error by 23%, with the original model untouched. The architecture change was postponed, which also kept the AI Model Development Cost well below the original budget.
That is the recurring lesson. The cheapest accuracy gain is almost always sitting in the data, not the algorithm.
How Does Data Quality and AI Model Performance Connect?
Data quality and AI model performance are linked through one mechanism: a model minimizes error against its training data, so whatever is wrong in the data becomes the target the model is optimized toward. Garbage in is not just garbage out. It is garbage out at scale, with confidence scores attached.
AI model accuracy is the most visible casualty. Gartner research cited across the industry shows that around 20% data contamination can lower model accuracy by roughly 10%. For a fraud model processing millions of transactions, that gap is real money.
AI model reliability suffers next. A model trained on inconsistent data behaves unpredictably on edge cases, which is exactly where leaders need it to be trustworthy.
Model generalization is the quiet third victim. If your training data only reflects last year’s customers, the model will perform well in testing and poorly in the real world, because the real world has moved on.
Which Dimensions of Data Quality Matter Most for AI?
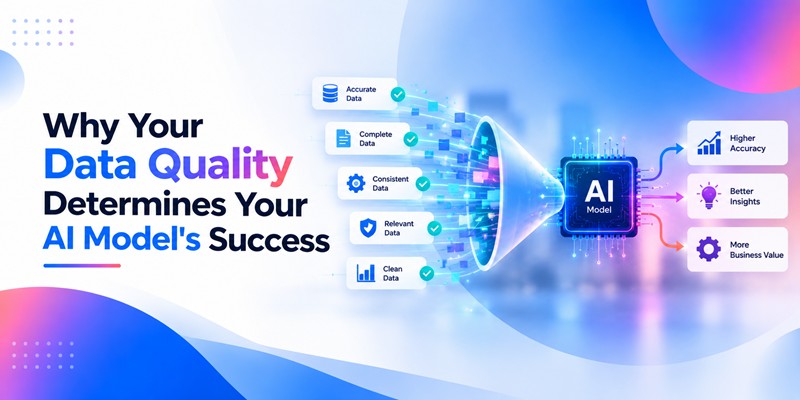
Five dimensions decide most AI outcomes: data accuracy, data completeness, data consistency, data integrity and representativeness. The importance of data quality in AI is not evenly spread across them, so knowing which one is hurting you saves months.
Data accuracy is whether each value reflects reality. A wrong price, a misspelled city or a mislabeled image all count. Accuracy errors are the most common and usually the cheapest to fix at the source.
Data consistency is whether the same thing is recorded the same way everywhere. Dates in three formats, customer names in two systems and currencies mixed in one column are the classic AI killers.
Data integrity is whether relationships hold. Orders that reference customers who do not exist, or events timestamped before their causes, break the logic a model is trying to learn.
Representativeness is whether the data covers the situations the model will face. This dimension drives model generalization more than any other and is the one most teams forget to measure.
What Happens When Training Data Is Biased or Incomplete?
Biased or incomplete training data produces a model that is confidently wrong for the people and scenarios it never saw. The model does not know what is missing. It simply treats the absence as if those cases do not exist.
An MIT study of more than 300 enterprise AI deployments found only about 5% reached production with measurable return. The common thread in the failures was not the algorithm. It was training data that did not match operating conditions.
Incomplete data also inflates testing results. If your test set shares the same blind spots as your training set, accuracy looks excellent right up until launch day.
For regulated sectors such as lending, hiring and healthcare, biased data is a legal liability as well as a performance problem. Documenting data lineage and coverage is now part of responsible custom AI model development, not an optional extra.
How Do You Measure Data Quality Before Training a Model?
You measure data quality before training by profiling the dataset against the five dimensions above and scoring each one, so the team has a number to improve rather than a feeling. A one-week data audit routinely prevents a six-month model rebuild.
Start with a profiling pass. Count nulls per column, duplicate rows, out-of-range values and format variants. Most teams are surprised by what they find in the first hour.
Then sample and hand-check labels. Pull 200 to 500 records, have two reviewers label them independently and measure agreement. Anything below 90% agreement means your labels are too noisy to trust.
Finally, compare the training distribution against live production data. If the shapes differ, your model will not generalize, no matter how good its test score looks.
Data Quality vs. Model Tuning: Which Delivers More?
Data quality work delivers more for most organizations because it fixes the ceiling, while model tuning only pushes you closer to a ceiling that bad data has already lowered. Here is how the two investments compare in practice.
| Factor | Improving data quality | Tuning or swapping the model |
| Typical accuracy gain | 10% to 30% on noisy datasets | 1% to 5% on the same data |
| Time to see results | 1 to 4 weeks | 2 to 8 weeks per iteration |
| Effect on model generalization | Strong and lasting | Limited by data coverage |
| Effect on AI model reliability | Reduces unpredictable edge-case failures | Rarely changes edge-case behavior |
| Reusability | Benefits every model and report using the data | Benefits one model only |
| Impact on AI Model Development Cost | Lowers rework and retraining spend | Often raises compute and tooling spend |
| Risk of regression | Low | Medium to high |
| Best for | Any team with real-world data | Teams with already clean, representative data |
The honest answer is that you need both eventually. The order matters. AI model performance optimization through tuning only pays off once the data stops lying to the model.
How Do You Build a Data Quality Pipeline That Keeps Models Healthy?
You build a durable data quality pipeline by validating data at the point of entry, monitoring it continuously in production and tying every model to the version of the data it was trained on. Quality is a process, not a cleanup project.
Validate at ingestion. Define rules for each field, such as required, type, range and format, and reject or quarantine records that fail. Catching a bad record at the door costs cents. Catching it after a model has learned from it costs weeks.
Monitor for drift. Customer behavior, pricing and language all change. Track the statistical profile of incoming data and alert when it moves away from what the model was trained on.
Assign ownership. Every critical dataset needs a named steward who is accountable for its quality score. Without a name attached, quality quietly becomes nobody’s job.
This is where experienced AI Integration services earn their fee: not in writing the model, but in wiring these checks into the systems your business already runs on.
When Should Leaders Invest in Data Before the Model?
Leaders should invest in data first whenever the project touches customer-facing decisions, regulated outcomes or revenue forecasts, because those are the cases where a wrong answer costs more than a late one. The only time to skip ahead is a low-stakes internal prototype meant to test an idea, not run a business.
For SMBs and startups, the stakes are different but the rule holds. You rarely have the budget to train twice. Spending the first 20% of the project on a data audit protects the other 80%.
For CTOs and CIOs, the signal is simple. If fewer than 12% of your peers consider their data AI-ready, per Informatica’s survey of chief data officers, then being in that minority is a competitive advantage in itself.
The question to ask any vendor proposing custom AI model development is not “which model will you use?” It is “what did you find when you audited our data, and what did you fix?”
Conclusion
AI data quality is the single largest controllable factor in whether your model reaches production and keeps delivering once it is there. The research is consistent, the cost figures are large and the fix is well understood. What separates winning teams from stalled pilots is simply doing the data work first.
Here is what to do this quarter:
- Run a data audit this month. Profile your top three AI-relevant datasets for accuracy, completeness, consistency, integrity and representativeness. Put a score on each.
- Fix the worst dimension before touching any model. In our experience that one fix delivers more than the next three model iterations combined.
- Assign a data owner per dataset. A name and a quality target, reviewed monthly.
- Add validation at ingestion and drift monitoring in production. Make quality a pipeline, not a project.
- Re-baseline model accuracy after the data fix. You will likely find the model you already have is better than you thought.
If you want a second set of eyes on your data readiness, Technobrave offers a structured AI data audit as the first step of every engagement. It usually takes two weeks and it changes the conversation about what your AI can actually do.